Auto Daily Rainfall
This is the second in a set of three projects demonstrating a 100% AI method to do large-scale Climate Data Rescue:
Robot Rainfall Rescue demonstrated the basic approach: How to fine-tune an ensemble of small Vision Language Models to convert a large collection of photographs of historical documents containing numerical weather records into computer-readable form.
This Project applies the approach to the 660,000 pages of the UK Daily Rainfall Reports (England and Wales). It demonstrates fine-tuning without any training data, and produces a full ensemble transcription.
Auto Daily Rainfall QC takes the raw transcriptions, applies metadata (locations and dates), does basic QC and deduplication, and outputs 73 million daily rainfall observations as ready-to-use Station Exchange Format (SEF) files.
This project uses an ensemble of small Vision Language Models (VLMs) to transcribe a collection of daily rainfall registers for England and Wales: about 660,000 scanned station-year images, each a dense grid of daily rainfall totals. Success means converting every image into a structured table of numbers that can be ingested into a database.
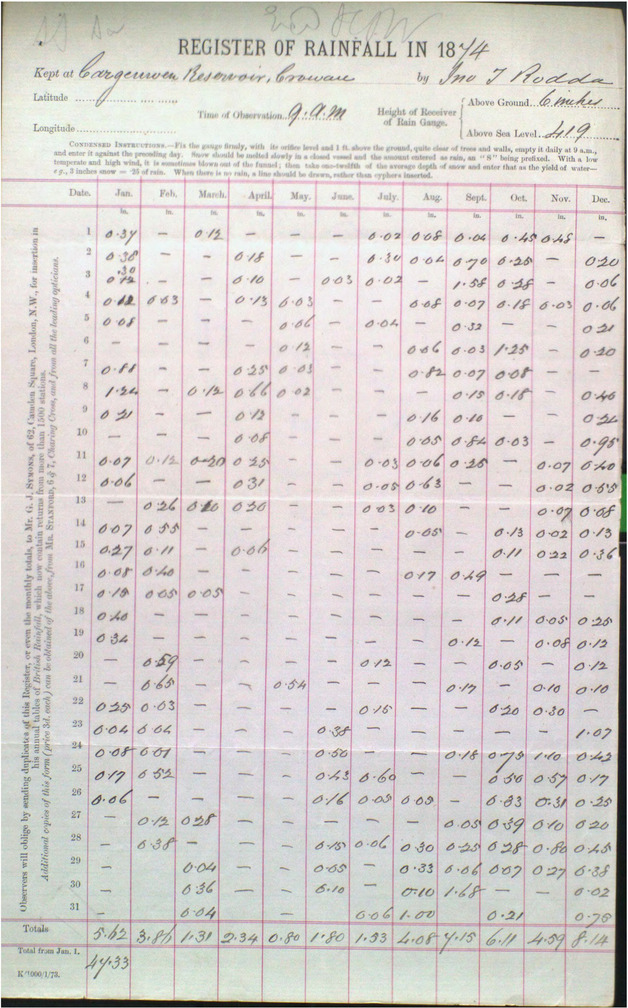
A single scanned daily rainfall register. Each image holds one station’s daily rainfall totals (mm) — rows for days 1–31, columns for the months, plus monthly totals. The task is to turn this into a table of numbers.
The approach
The fundamental method is the same as that applied in Robot Rainfall Rescue: We don’t try to impose our own structure on the problem. Instead we take small, open-weight VLMs, fine-tune them on the rainfall task, and let them read the images directly into JSON. The additional challenges for this project are threefold:
The images are more complex - more difficult for the VLMs to read. We deal with this by doing more fine-tuning.
We have many more images to read - time and cost become important factors. We deal with this by optimisation - reduced image size, maximum batch size, care in allocating jobs to GPUs.
We don’t have any ground-truth data to fine-tune to. We deal with this with a two-stage data-free tuning method - first we fine tune to synthetic images, then we fine tune to ensemble consensus.
The work proceeds in staged rounds, and — importantly — each round is driven by a notebook that you can open, read, and run.
Preparation — generate synthetic training data with known values, and import a small hand-transcribed test set for validation.
Zeroth order — measure the raw, un-fine-tuned models to establish a baseline.
First order — fine-tune every model on the synthetic data and re-measure.
Second order — build a consensus training set from where the first-order models agree on real images, fine-tune again on that, and re-measure.
Operations — run the finished ensemble over the full 660,000-image dataset.
The workflow overview explains how the notebooks fit together; the pages under it walk through each stage.
Does it work?
Yes. Measured on 64 real, hand-transcribed images (Ciara Ryan’s Irish daily rainfall sheets), the models improve dramatically across the rounds:
Model |
Zeroth order (raw) |
First order (fake) |
Second order (consensus) |
|---|---|---|---|
Granite |
46% |
92% |
95% |
Ministral |
62% |
85% |
94% |
Gemma-3 |
21% |
70% |
90% |
Gemma edge |
39% |
66% |
89% |
SmolVLM |
32% |
68% |
87% |
Per-cell accuracy against hand-transcribed ground truth.
The raw models are hopeless — the best gets under two thirds of the values right. After two rounds of fine-tuning, every model is in the high eighties or better, and an consensus that requires agreement between models does better still. The two-stage data-free tuning method is a powerful technique - despite having no ground-truth data we can fine-tune the VLM ensemble up to a sufficient quality for data rescue work.
It’s important to note that the method is not specific to this document type (the daily rainfall sheets). It should be possible to use the same technique on any document format.
Get started
Installation — set up the environment.
Workflow overview — the staged, notebook-driven pipeline.
How to reproduce and extend — code, compute, and credits.
Results
Raw transcriptions of the England and Wales daily-rainfall sheets. These are raw transcriptions - a 5 member ensemble of transcriptions of the 372 daily values from each of the 660,000 sheets. Few people will be interested in these, their main value is as the input to the next project in the chain, which turns them into useful observations.
Credits
This document is distributed under the terms of the Open Government Licence. Source code included is distributed under the terms of the BSD license.